LLM Inference Optimization Techniques

Inference optimization is a critical part of generative AI applications deployed in production. Using LLMs efficiently at scale is a challenge and many techniques have been developed over the last years to make inference faster and cheaper. I review these techniques in this article.

A Focus On LLMs Architecture

Large language models (LLMs) are all based on the transformer architecture invented in 2017 by Vaswani et al. The transformer architecture achieves superior accuracy, few-shot learning, and near-human abilities across diverse language tasks. However, these foundation models, often comprising tens to hundreds of billions of parameters, are costly to train and resource-intensive during inference. Inference costs escalate with long input contexts, which demand significant processing power due to large input data. This makes efficient inference a critical challenge, particularly in managing memory and compute resources.
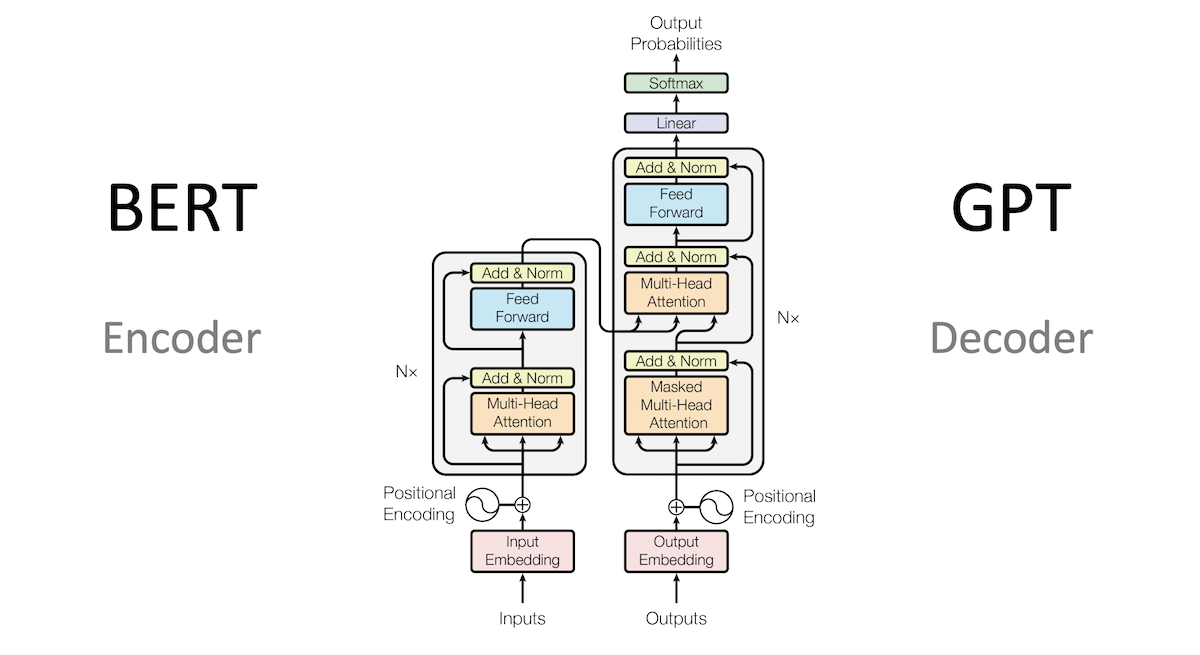
The Transformer Architecture

More specifically, most well-known LLMs, are decoder-only LLMs, like GPT-3, GPT-4, LLaMA, Mistral, DeepSeek, etc. These models are pretrained on a causal modeling task, functioning as next-word predictors. They process a sequence of tokens as input and produce following tokens autoregressively until a stopping condition is reached.

LLM inference in decoder-only models involves two key phases: the prefill phase and the decode phase. In the prefill phase, the model processes input tokens to compute intermediate states (keys and values) for generating the first new token. This phase, resembling a matrix-matrix operation, is highly parallelized and efficiently utilizes GPU capabilities. Conversely, the decode phase generates tokens, one at a time, relying on previous tokens’ states. This matrix-vector operation is memory-bound, as data transfer to the GPU, rather than computation speed, primarily dictates latency, leading to underutilized GPU compute power.

Optimizing the decode phase is a focal point for addressing inference challenges. Solutions include developing efficient attention mechanisms and better management of keys and values to reduce memory bottlenecks. The post highlights practical approaches to enhance inference performance, assuming readers have a basic understanding of the transformer architecture and attention mechanisms. These optimizations are crucial for improving throughput and reducing latency in real-world LLM deployments.

A further complication arises from the use of different tokenizers across LLMs, which affects token comparability. Tokens, roughly equivalent to four English characters, vary in representation depending on the tokenizer, making direct comparisons of inference throughput (e.g., tokens per second) misleading. This variability underscores the need for standardized evaluation metrics to accurately assess and compare LLM performance during inference.

Batching

Batching is a key strategy for improving GPU utilization and throughput in large language models (LLMs). By processing multiple requests simultaneously using the same model, batching distributes the memory cost of model weights across requests, allowing larger batches to leverage more GPU compute power. However, there’s a limit to batch size, as excessively large batches can cause memory overflow due to the memory demands of LLMs, particularly related to key-value (KV) caching (more on this later).
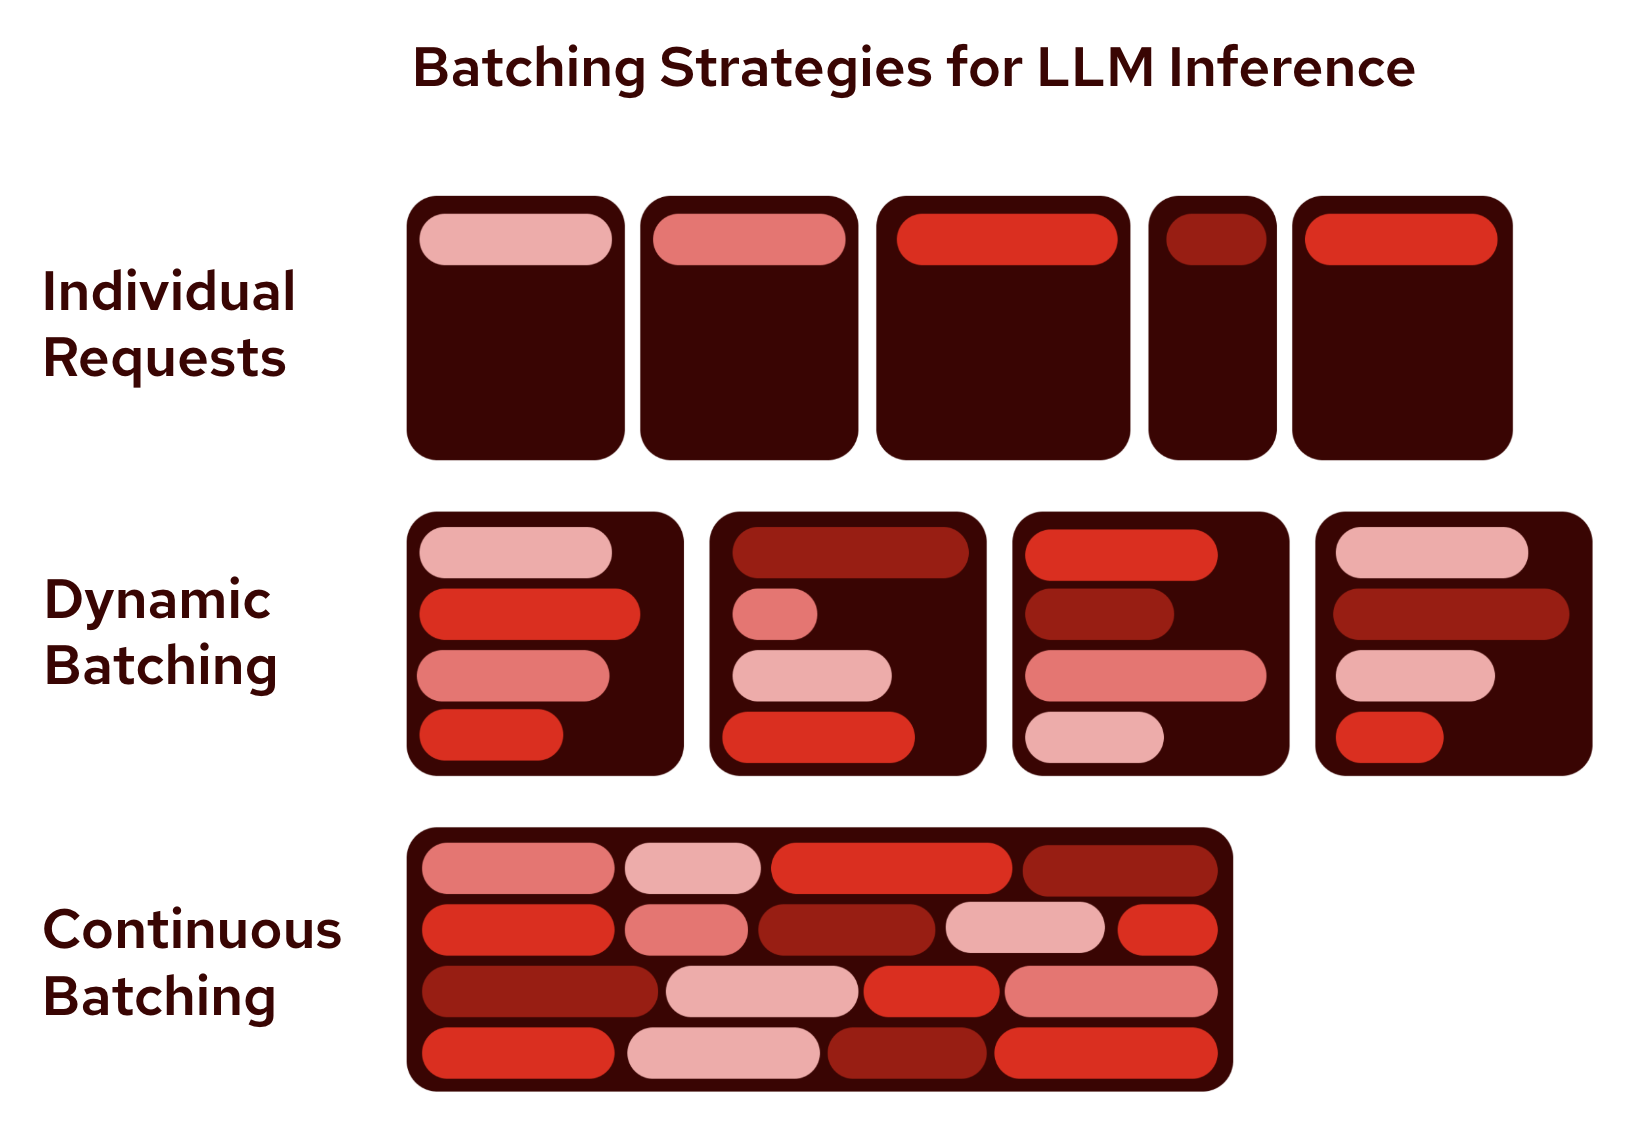
Batching Techniques

Traditional or static batching has limitations because requests within a batch often generate different numbers of completion tokens, leading to varied execution times. This causes all requests to wait for the slowest one to complete, which can be problematic when generation lengths vary significantly. To address this, advanced techniques like in-flight batching have been developed to optimize performance.

In-flight batching, also known as continuous batching, tackles the challenges posed by the dynamic nature of LLM workloads, which can range from simple chatbot responses to complex document summarization or code generation. These tasks produce outputs of vastly different sizes, making it hard to batch and execute requests efficiently in parallel. Unlike static batching, in-flight batching allows the server to evict completed sequences from the batch immediately and start processing new requests while others are still in progress. This approach significantly boosts GPU utilization by adapting to the varying execution times of requests in real-world scenarios.

Multi-GPU Deployment With Model Parallelization

Model parallelization is a critical strategy for managing the memory and computational demands of large-scale machine learning models by distributing them across multiple GPUs. This approach allows for the handling of larger models or input batches that exceed the memory capacity of a single device, making it essential for both training and inference when memory constraints are tight. Various techniques exist for splitting model weights, including pipeline parallelism, tensor parallelism, and sequence parallelism, each addressing different aspects of model distribution. Unlike data parallelism, which focuses on replicating model weights across devices to process larger input batches during training, these methods are more relevant for reducing memory footprints during both training and inference.
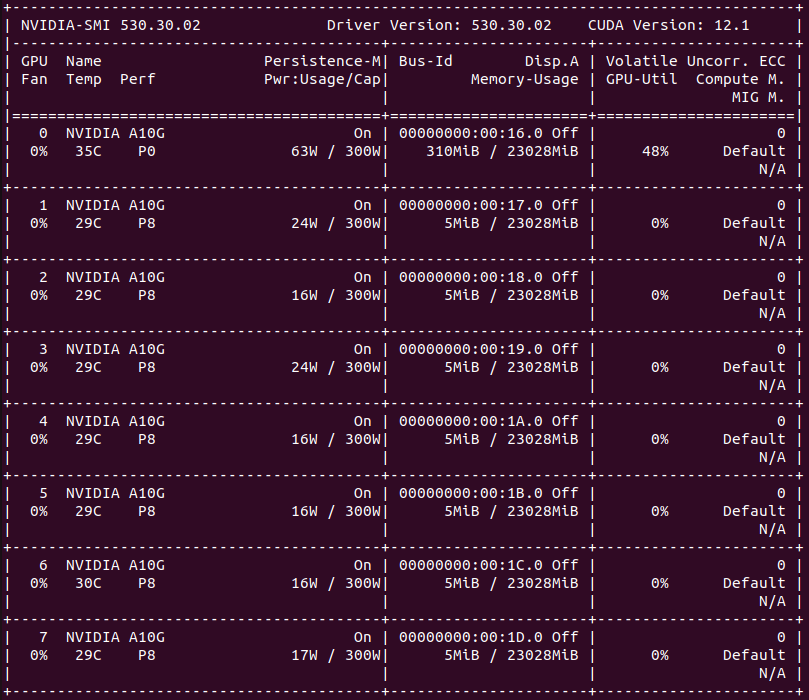
Multiple NVIDIA GPUs

Pipeline parallelism divides the model vertically into sequential chunks, with each chunk containing a subset of layers assigned to a separate device. For instance, in a four-way pipeline setup, each device handles a quarter of the model’s layers, passing outputs to the next device in sequence. While this significantly reduces per-device memory requirements, it introduces inefficiencies known as “pipeline bubbles,” where devices may idle while waiting for outputs from previous layers. Microbatching, which splits input batches into smaller sub-batches for sequential processing, can reduce these bubbles but not eliminate them entirely, as idle times persist during forward and backward passes.

Tensor parallelism, in contrast, shards individual layers horizontally into smaller computational blocks that can be executed independently across devices. This is particularly effective for transformer components like attention blocks and multi-layer perceptrons (MLPs), where, for example, different attention heads can be assigned to separate devices for parallel computation. However, tensor parallelism is less effective for operations like LayerNorm and Dropout, which cannot be easily divided and must be replicated across devices, leading to redundant memory usage for storing activations. This limitation highlights the need for complementary approaches to optimize memory efficiency.

Sequence parallelism addresses the memory inefficiencies of operations like LayerNorm and Dropout by partitioning them along the input sequence dimension, leveraging their independence across sequence elements. This method reduces the memory footprint of redundant activations, making it a valuable complement to tensor parallelism. These parallelization techniques are not mutually exclusive and can be combined to optimize large language models (LLMs) further. Additionally, specific optimization strategies for the attention module can enhance scalability and reduce per-GPU memory demands, enabling more efficient training and inference for large models.

Attention Optimization

The 2017 paper Attention Is All You Need by Vaswani et al. introduced the Transformer model, with self-attention as its cornerstone. Self-attention enables the model to assess the relevance of different words in a sentence relative to each other, enhancing contextual understanding for tasks like natural language processing. The paper formalized self-attention, particularly through the scaled dot-product attention (SDPA) mechanism, which maps query and key-value pairs to an output, making it a pivotal component in modern neural networks. Here are some of the most important techniques to optimize attention computations:

Multi-head attention (MHA) builds on SDPA by running multiple attention operations in parallel, each with distinct projections of query, key, and value matrices. These parallel operations, or “heads,” focus on different representational subspaces, enriching the model’s understanding of the input. The outputs from these heads are concatenated and linearly projected, maintaining computational efficiency comparable to single-head attention by reducing the dimensionality of each head (e.g., dividing the model dimension by the number of heads, such as 8).

Multi-query attention (MQA) optimizes MHA for inference by sharing key and value projections across multiple attention heads while keeping multiple query projections. This reduces memory bandwidth demands and the size of the key-value (KV) cache, enabling larger batch sizes and better compute utilization. However, MQA may slightly reduce accuracy, and models leveraging it require training or fine-tuning with MQA enabled to maintain performance.

Grouped-query attention (GQA) balances MHA and MQA by grouping query heads and sharing key-value projections within each group, achieving near-MHA quality with computational efficiency closer to MQA. Models like Llama 2 70B use GQA, and those trained with MHA can be adapted to GQA with minimal additional training. Both MQA and GQA reduce KV cache memory demands, though further optimizations in cache management remain necessary.

FlashAttention enhances attention mechanisms by reordering computations to leverage GPU memory hierarchies more effectively. Unlike traditional layer-by-layer processing, FlashAttention fuses operations and uses “tiling” to compute small portions of the output matrix at once, minimizing memory read/write operations. This I/O-aware, exact attention algorithm integrates seamlessly into existing models without modifications, offering significant speedups by optimizing data movement.

Key-Value Caching

KV caching is a critical optimization technique used during the decode phase of large language models (LLMs) to improve the efficiency of self-attention computations. In this phase, each generated token depends on the key (K) and value (V) tensors of all previous tokens, including those computed during the prefill stage and subsequent decode steps. Instead of recomputing these tensors for every token at each time step, KV caching stores them in GPU memory, appending new tensors to the cache as they are computed. Typically, a separate KV cache is maintained for each layer of the model, significantly reducing redundant computations and speeding up the decoding process.
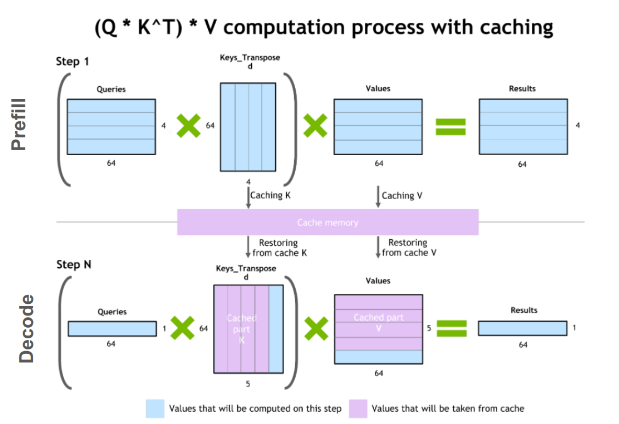
Key-Value Caching

The memory requirements for LLMs on GPUs are primarily driven by two components: model weights and the KV cache. Model weights, which consist of the model’s parameters, occupy substantial memory; for instance, a 7-billion-parameter model like Llama 2 7B in 16-bit precision requires approximately 14 GB. The KV cache, on the other hand, stores self-attention tensors to avoid recomputation, with its size determined by factors such as the number of layers, attention heads, head dimensions, and precision. For each token, the cache size is calculated as 2 * num_layers * (num_heads * dim_head) * precision_in_bytes, where the factor of 2 accounts for both K and V matrices. For a batch of inputs, the total KV cache size scales with batch size and sequence length, potentially reaching significant sizes, such as ~2 GB for a Llama 2 7B model with a sequence length of 4,096 and batch size of 1.

Managing the KV cache efficiently poses challenges due to its linear growth with batch size and sequence length, which can limit throughput and complicate handling long-context inputs. A common inefficiency arises from static over-provisioning, where memory is reserved for the maximum supported sequence length (e.g., 2,048 tokens), regardless of the actual input size. This leads to significant memory waste or fragmentation, as much of the reserved space often remains unused throughout the request’s lifetime, tying up valuable GPU memory resources.

To address these inefficiencies, the PagedAttention algorithm introduces a novel approach inspired by operating system paging. It divides the KV cache into fixed-size blocks, each representing a set number of tokens, which can be stored non-contiguously in memory. A block table tracks these blocks, fetching them as needed during attention computations. As new tokens are generated, additional blocks are allocated dynamically. This method minimizes memory wastage by eliminating the need for contiguous allocation and over-provisioning, enabling larger batch sizes and improving throughput, thus making it a significant advancement in managing KV cache memory for LLMs.

Model Optimization

In this section I discuss various techniques for optimizing large language models (LLMs) to reduce their memory consumption and enhance performance on GPUs. Key methods include quantization, sparsity, and distillation, each targeting different aspects of model efficiency. These techniques modify model weights, leverage GPU hardware acceleration, and transfer knowledge to smaller models, enabling larger models to run on limited hardware while maintaining performance. These methods can degrade the accuracy of the model, so they should be used with caution.

Quantization reduces the precision of a model’s weights and activations, typically from 32 or 16 bits to 8 or fewer bits, allowing models to occupy less memory and transfer data more efficiently. While quantizing weights is straightforward due to their fixed nature post-training, quantizing activations is more complex due to outliers that expand their dynamic range. Techniques like LLM.int8() address this by selectively applying higher precision to certain activations, or by reusing the dynamic range of quantized weights for activations, though GPUs may require converting weights back to higher precision for operations.

Sparsity involves pruning model values close to zero, creating sparse matrices that require less memory. GPUs support structured sparsity, such as representing two out of every four values as zeros, which accelerates computations. Combining sparsity with quantization can further enhance execution speed. Research continues to explore optimal sparse representations for LLMs, indicating a promising avenue for improving inference speeds.

Distillation transfers knowledge from a larger “teacher” model to a smaller “student” model, compressing size while preserving performance. For example, DistilBERT achieves a 40% size reduction and 60% speed increase compared to BERT, retaining 97% of its capabilities. Distillation can involve mimicking the teacher’s outputs or using teacher-generated data for training, with methods like “Distilling Step by Step!” incorporating rationales for efficient learning. However, restrictive licenses on many advanced LLMs limit the availability of suitable teacher models for distillation.

Speculative Inference

Speculative inference, also known as speculative sampling or assisted generation, is a method to parallelize the execution of autoregressive large language models (LLMs) like GPT-style models, which typically generate text token by token. In standard execution, each token depends on all prior tokens for context, making parallel generation impossible as the nth token must be generated before the (n+1)th. Speculative inference addresses this by using a “cheaper” draft model to predict multiple future tokens simultaneously, which are then verified or rejected in parallel by the main model, allowing faster text generation.

The process involves generating a draft continuation of several tokens using a less resource-intensive method, followed by parallel verification by the main model using the draft as speculative context. If the verification model matches the draft tokens, they are accepted; otherwise, non-matching tokens and subsequent ones are discarded, and the process repeats with a new draft. Draft tokens can be generated using various approaches, such as training multiple models, fine-tuning multiple heads on a pretrained model to predict future tokens, or employing a smaller draft model alongside a larger, more capable verification model, each with its own tradeoffs.

Disaggregated Inference

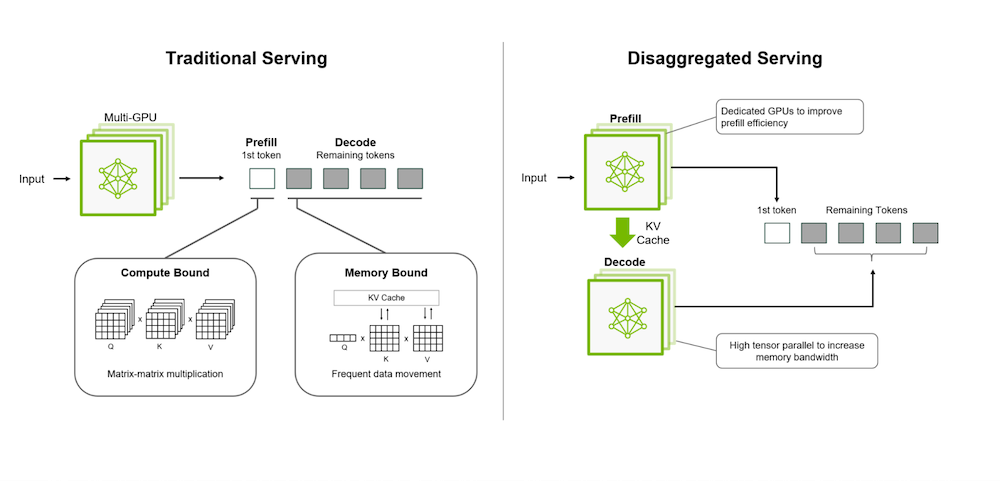
Disaggregated inference is a technique where the computational tasks are split across different hardware to optimize performance, cost, and resource use. Specifically, it separates the prefilling and decoding phases. By disaggregating these phases, each can be assigned to hardware best suited for its computational demands, improving efficiency and scalability.
Disaggregated Inference

Prefilling is compute-intensive, requiring significant matrix multiplications to process the entire input prompt and produce KV caches. This phase benefits from high-performance hardware like GPUs or TPUs, which excel at parallel computations. Since prefilling is a one-time task per inference request, it can be offloaded to a centralized, powerful compute node optimized for such workloads. This setup allows for faster processing of large prompts and reduces the burden on less capable devices, making it ideal for cloud-based or data-center environments where high-throughput hardware is available.

Decoding, in contrast, is memory-bound and involves iterative token generation, relying heavily on accessing the KV caches. It requires less computational power but needs fast memory access, making it suitable for less powerful, memory-optimized hardware like CPUs or edge devices. By moving decoding to separate hardware—potentially closer to the end user, such as on-premises servers or edge devices—disaggregated inference reduces latency and network bandwidth demands. This separation enables flexible deployment, where prefilling runs on high-end cloud servers and decoding occurs on local or edge devices, optimizing resource allocation and enabling efficient scaling for applications like real-time chatbots or interactive AI systems.

Conclusion

Many inference optimization techniques have been invented recently in order to improve the performance of LLMs.

Implementing these techniques requires a deep understanding of the LLM architecture and the hardware you are using, so it is generally easier to use an existing inference engine that has already implemented these techniques like vLLM, TensorRT-LLM, LMDeploy, etc.
GenAI Inference Engines: TensorRT-LLM vs vLLM vs Hugging Face TGI vs LMDeploy

The rise of generative AI (GenAI) has transformed industries, from natural language processing to creative content generation. However, deploying these powerful models efficiently at scale remains a challenge.

Inference engines play a critical role in optimizing performance, reducing latency, and maximizing resource utilization. In this article, I look at four leading solutions: TensorRT-LLM, vLLM, Hugging Face TGI, and LMDeploy.

Each brings unique strengths to the table, whether it’s NVIDIA’s hardware-accelerated precision, vLLM’s innovative memory management, TGI’s production-ready ecosystem, or LMDeploy’s focus on speed and simplicity. I compare these engines to help you find a fit for your GenAI workloads.

TensorRT-LLM: NVIDIA’s Powerhouse for Optimized Inference

TensorRT-LLM is NVIDIA’s answer for making large language models run fast and smooth. Built on their TensorRT framework, it’s designed to squeeze every drop of performance out of NVIDIA GPUs. It does this with tricks like layer fusion, precision tweaking (FP16, INT8, FP8…), and kernel optimization that cuts down compute time without breaking the model’s accuracy.

It’s not just about speed. TensorRT-LLM handles big models efficiently by managing memory smartly, so you don’t crash mid-run. It also supports dynamic batching, letting you process multiple requests at once without running out of memory. If you’re already using NVIDIA hardware, it’s a no-brainer as it’s tightly glued to their ecosystem, like CUDA and cuDNN, and it even integrates with NVIDIA’s Triton Inference Server and NVIDIA Dynamo.

That said, it’s not perfect for everyone. Setup can be a pain if you’re not comfortable with NVIDIA’s tools, and it’s less flexible if you’re on non-NVIDIA hardware. Still, for raw power and optimization on NVIDIA GPUs, it’s tough to beat.

vLLM: High-Throughput Inference with PagedAttention

vLLM is very good at handling high volumes of inference jobs fast. It’s an open-source project that shines when you need high throughput without slowing down. The secret sauce is PagedAttention, a trick that manages memory way better than most. Instead of loading everything at once and eating up RAM, it splits the key-value caches into chunks, only grabbing what’s needed. Less waste, more speed.

It’s very flexible too. Works with popular models like LLaMA or Mistral right out of the box, and it supports many hardware, including NVIDIA or AMD GPUs. You also get dynamic batching to group requests efficiently, keeping the pipeline running smoothly. Setup is pretty straightforward if you’re used to Python and PyTorch.

The primary limitation of vLLM is its relative immaturity in the market, which means it may not yet offer the comprehensive feature set available in more established solutions. However, for organizations seeking an efficient solution that delivers high-performance inference, vLLM represents an excellent choice.

Hugging Face TGI: A Production-Ready Solution for Text Generation

Hugging Face TGI (Text Generation Inference) is made for people who want to get models up and running without a headache. It’s a tool built by the Hugging Face team, so it plays nice with their massive library of pre-trained models—think BERT, GPT, and more. It’s designed for real-world use, like powering chatbots or apps where text generation has to work fast and not crash.

TGI handles the heavy lifting with features like continuous batching, which keeps the system busy by swapping in new requests as old ones finish. It supports GPU acceleration and can scale up if you’ve got the hardware. Plus, it’s got built-in safety—like filtering out bad outputs—which is handy for production. You can deploy it with Docker in a few steps, so it is relatively easy to set up.

The catch? It’s tied to Hugging Face’s ecosystem, so if you’re not already in that world, it might feel restrictive. Still, for a plug-and-play option that’s ready to use, TGI is a great choice.

LMDeploy: Efficient Deployment with Superior Decoding Speed

LMDeploy is a toolkit from the MMRazor and MMDeploy teams, built to compress, deploy, and run large language models without fuss. What makes it stand out? It has got excellent decoding speed—up to 1.8x more requests per second than vLLM on an A100 GPU. That is thanks to tricks like persistent batching, blocked KV caching, and slick CUDA kernels that keep the GPU busy.

It has two engines: TurboMind for max performance and a PyTorch one for easier tinkering. TurboMind is the star here—it pushes 4-bit inference 2.4x faster than FP16, and it handles big models like Llama-2 70B with ease. You can also quantize weights and KV caches to save memory without harming accuracy. Deployment is a breeze too—one command sets up a server across multiple machines if you need it. Plus, it remembers chat history in multi-round talks, so it doesn’t waste time redoing old work.

The downside? TurboMind is picky—it doesn’t play nice with sliding window attention models like Mistral yet. And if you’re not on NVIDIA GPUs, you’re stuck with the slower PyTorch engine. Still, for speed and simplicity on the right hardware, LMDeploy is a great choice.

Performance Comparison: Latency, Throughput, and Scalability

Here is how these engines stack up on latency (how fast one request finishes), throughput (how many requests they can ingest), and scalability (how well they handle bigger loads or more hardware).

TensorRT-LLM shines on latency if you have NVIDIA GPUs. It’s highly optimized for NVIDIA hardware, so single requests finish quickly: under 50ms for most models on an A100. Throughput is excellent too, especially with dynamic batching. Benchmarks by BentoML show that this engine reaches 700 tokens per second at 100 concurrent users for Llama 3 70B Q4 on an A100 80GB GPU. TensorRT-LLM performs strongly in scenarios with long inputs and high request rates, offering good throughput. Scalability on multiple GPUs is supported out of the box with excellent performance.

vLLM has good throughput too, particularly in decode-heavy workloads, with high throughput and low latency after recent updates. Benchmarks by BentoML show that this engine reaches 600-650 tokens per second at 100 concurrent users for Llama 3 70B Q4 on an A100 80GB GPU. Latency is good but not as good as TensorRT-LLM: around 60-80ms for solo runs. It scales well across GPUs, even mixing brands, but it’s less polished for huge setups.

Hugging Face TGI performs similarly to vLLM, providing a balance of performance and ease of use. Latency is decent: 50-70ms on a good GPU. Benchmarks by BentoML show that this engine reaches 600-650 tokens per second at 100 concurrent users for Llama 3 70B Q4 on an A100 80GB GPU. It’s built to scale for production, so it handles more users or machines smoothly, especially with Docker.

LMDeploy wins on decoding speed. It excels in token generation rate, especially for smaller models, and has low Time to First Token (TTFT) for quantized large models. Latency is low: 40-60ms. And throughput is excellent. Benchmarks by BentoML show that this engine reaches 700 tokens per second at 100 concurrent users for Llama 3 70B Q4 on an A100 80GB GPU. Scaling is easy with its server setup, but it leans hard on NVIDIA GPUs for the best results; PyTorch mode lags behind.

Bottom line: TensorRT-LLM and LMDeploy lead on raw speed. Your pick depends on your hardware and how many requests you are handling.

Quantization Capabilities

Quantization reduces model precision to lower memory usage and speed up inference, which is important for resource-constrained environments. Here’s how each engine performs:

TensorRT-LLM supports FP8, FP4, INT4 with Activation-aware Weight Quantization (AWQ), and INT8 with SmoothQuant, offering robust options for optimizing NVIDIA GPU performance.

vLLM provides flexibility with GPTQ, AWQ, INT4, INT8, and FP8, adapting to various hardware and precision needs.

Hugging Face TGI integrates bitsandbytes for 8-bit and 4-bit quantization and GPT-Q for weight-only quantization, suitable for production deployments.

LMDeploy offers 4-bit AWQ, 8-bit quantization, and online INT8/INT4 KV cache quantization, enhancing efficiency for large models on limited hardware.

Hardware Compatibility

Hardware support determines where you can deploy these engines, impacting scalability and performance:

TensorRT-LLM is exclusive to NVIDIA CUDA, leveraging GPU accelerators for high performance.

vLLM supports NVIDIA CUDA, AMD ROCm, AWS Neuron, and CPU, offering broad compatibility for diverse setups.

Hugging Face TGI works with NVIDIA CUDA, AMD ROCm, Intel Gaudi, and AWS Inferentia, providing flexibility for various hardware environments.

LMDeploy is optimized for NVIDIA CUDA, ensuring top performance on NVIDIA GPUs but with limited support for other platforms.

Ease of Use

The setup and integration process can affect development timelines. Here’s how each engine fares:

TensorRT-LLM requires converting checkpoints, building the TensorRT engine, and configuring parameters, making it challenging and time-consuming for engineers.

vLLM is user-friendly with comprehensive documentation, easy installation, and seamless Python library integration.

Hugging Face TGI benefits from Hugging Face’s ecosystem, offering pre-built Docker images and thorough documentation for quick deployment.

LMDeploy features a simple setup with a single command to launch the server and Python APIs for customization, balancing ease with flexibility.

Conclusion

Picking the right engine depends on your use case, hardware, and skills.

TensorRT-LLM is your go-to inference engine if you are running big models on NVIDIA GPUs and need every ounce of speed (think low-latency applications like real-time chatbots or AI assistants where replies have to be generated in milliseconds). It’s perfect for companies already deep in NVIDIA’s world, but it might be overkill if you are looking for simplicity.

vLLM is a great trade-off between speed and simplicity. It works really well for startups or researchers who want something flexible and quick to set up.

Hugging Face TGI is equivalent to vLLM in terms of speed and simplicity. It’s easy to deploy, scales smoothly, and ties into Hugging Face’s model hub, so it’s ideal for teams wanting a no-fuss solution.

LMDeploy shines on performance, like TensorRT-LLM. It suits users with NVIDIA GPUs who want simple setup and top performance, but it’s less handy if your models don’t play nice with TurboMind.

Installing and Deploying LLaMA 3.1 405B Into Production on GCP Compute Engine

LLaMA 3.1 405b is a large language model developed by Meta AI, representing one of the largest openly available AI models in terms of parameter size, with 405 billion parameters. It’s part of the Llama 3.1 family, which includes models of different sizes (8B, 70B, and 405B parameters).

The 405B version is particularly notable for its scale, aiming to match or even surpass the performance of some of the top closed-source models like GPT-4 in various benchmarks, indicating its state-of-the-art capabilities in language understanding, generation, and other tasks. Llama 3.1 models are designed with enhanced multilingual support, capable of understanding and generating text in multiple languages, which broadens its applicability across different regions and user bases.

In this article, I show how to install and deploy LLaMA 3.1 405B into production on Google Cloud Platform (GCP) Compute Engine. I first talk about hardware requirements, then instance provisioning on GCP, and deployment and quantization with vLLM.

LLaMA 3.1 405B: hardware requirements

The hardware requirements for running Llama 3.1 405B are quite extensive due to its size and complexity. As usual when deploying LLMs, the most complex part is the GPU. You will need a lot of VRAM (i.e. GPU memory) to deploy this model:

  • In fp16 mode (which is the default mode for this model), the model requires around 972GB of VRAM
  • In fp8 mode, using quantization, it requires around 486GB of VRAM
  • Using 4-bit quantization, the VRAM further reduces to about 243GB

Given these needs, you’d typically look at setups like:

  • 8 x AMD MI300 192GB GPUs for 16-bit mode.
  • 8 x NVIDIA A100/H100 80GB GPUs for 8-bit mode.
  • 4 x NVIDIA A100/H100 80GB GPUs for 4-bit mode.

As usual, you have to be careful about quantization and make sure that the quality of the model does not suffer too much. In my test, the fp8 quantization does not seem to harm the quality of the model, so I am going to use it in this article.

Provisioning an Instance for LLaMA 3.1 405B on GCP Compute Engine

Google Cloud Platform (GCP) is an interesting provider for deploying and scaling your AI workloads. They are relatively cheap and have a good GPU offer (NVIDIA H100 80GB, NVIDIA A100 80GB, NVIDIA V100, NVIDIA L4, NVIDIA T4…).

They are also quite flexible in terms of instance choices. For example you can provision instances with one or more H100 GPUs: 1xH100, 2xH100, 4xH100, or 8xH100.

You might not be allowed to provision GPU instances if your account is new though and if that’s the case you will want to go through support to ask for a quota increase.

As a first step you will want to create a new project on GCP. Then you will want to enable the Compute Engine API for your project. You can do this by going to the API Library in the GCP Console and searching for “Compute Engine”. Click on it and then click on “Enable” to activate the API.

Once you have enabled the API, you will be able to create a new instance. You can do this by going to the “VM instances” section in the GCP Console and clicking on “Create instance”.

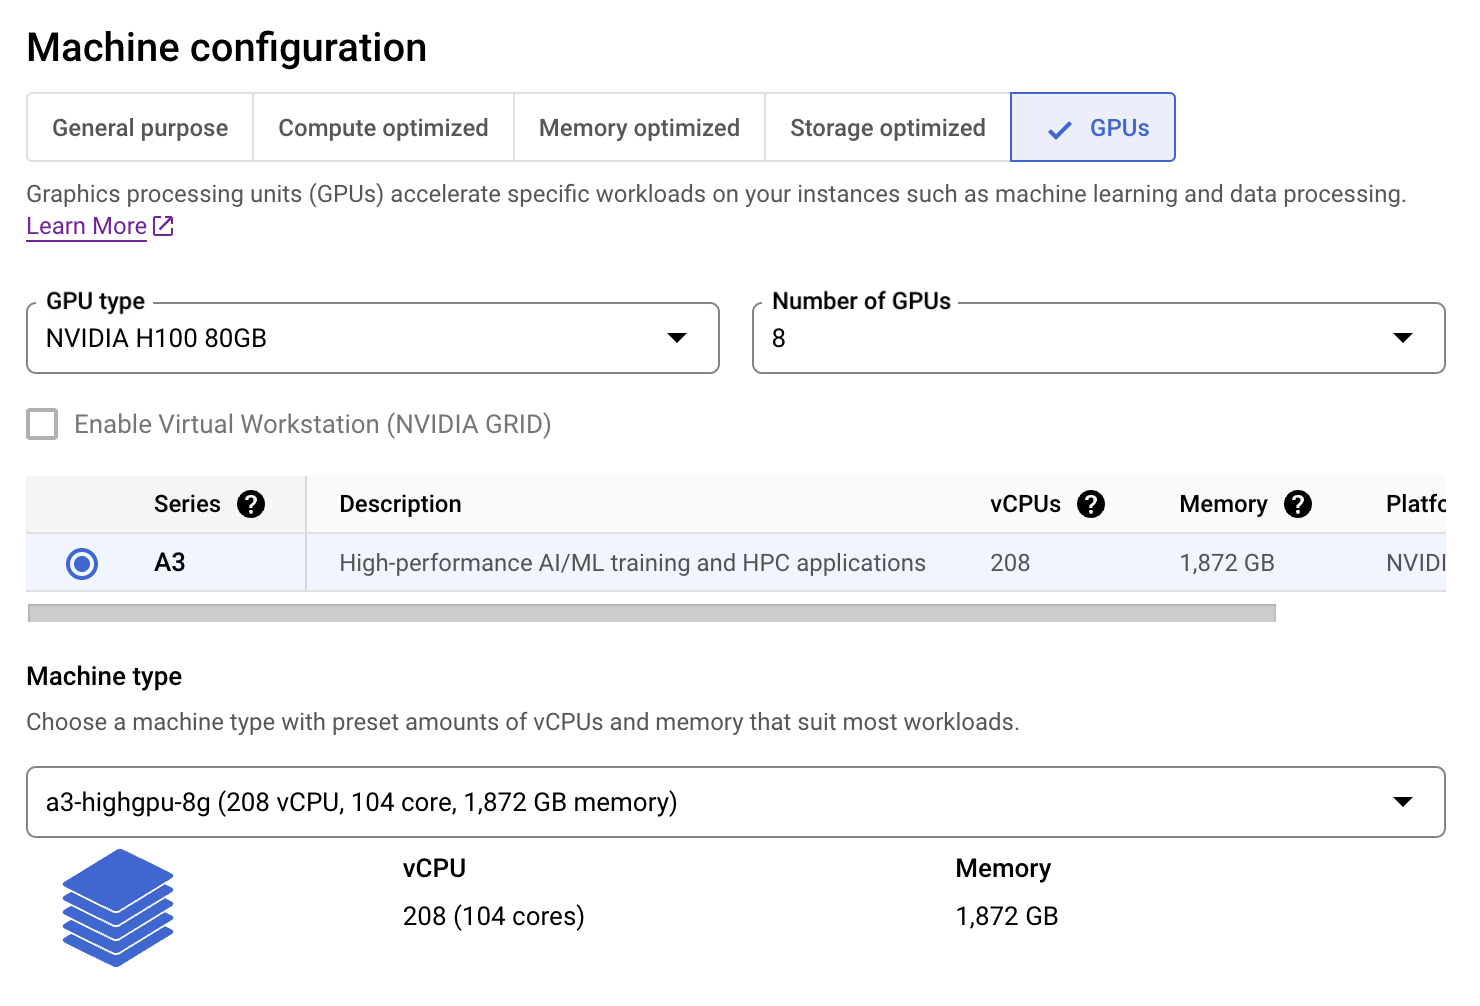
You will then be asked to choose a machine type. For LLaMA 3.1 405B in fp8 mode, you will want to choose an a3-highgpu-8g machine with 8xH100 GPUs.

GCP Instance for LLaMA 3.1 405B

You will then be able to set many details for your VM like networking, storage, etc. I am not going to review all these settings in this article, but I will focus on the image type and storage.

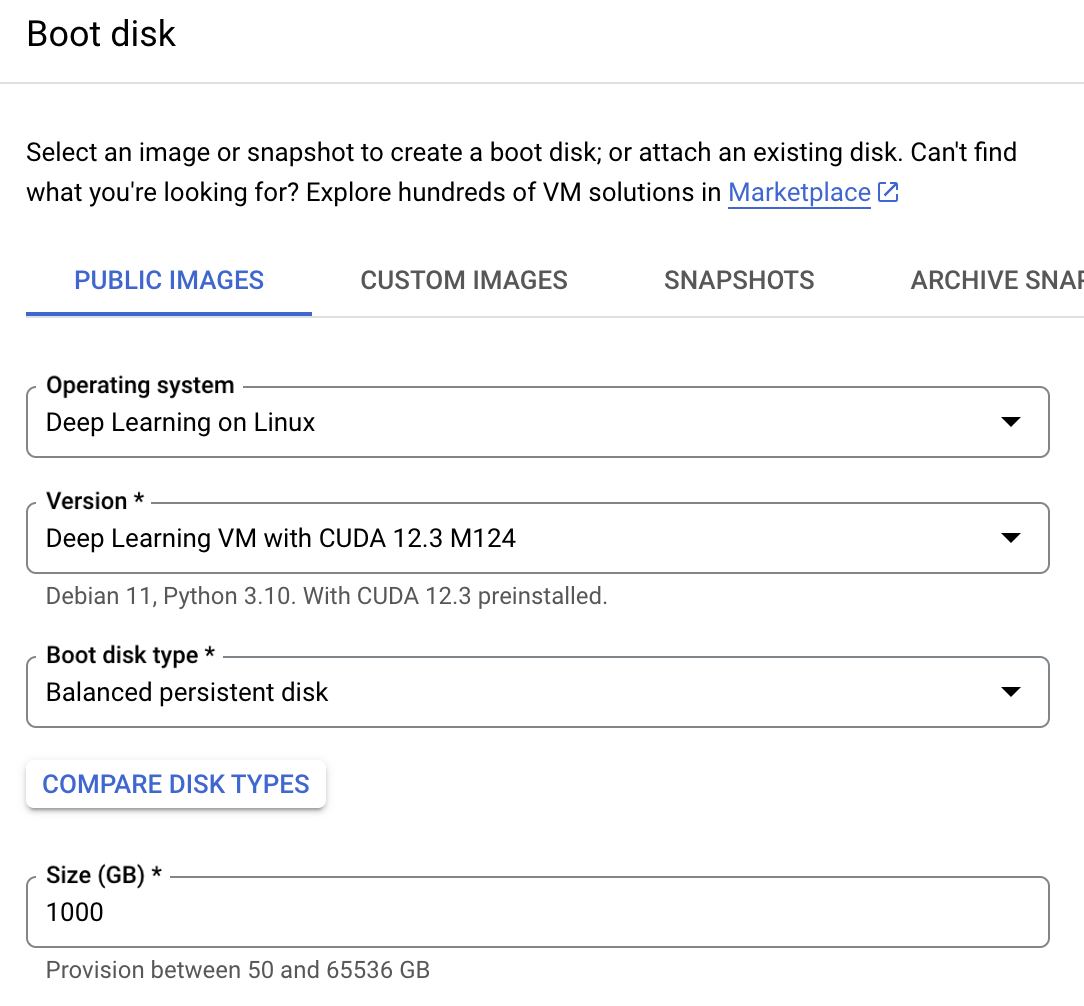
In order to download the LLaMA 3.1 405B model weights in fp8 format, you will need at least 500GB of disk space. I also recommend that you use a Linux Deep Learning image with CUDA 12 already installed as it can save some work later. You can achieve that in the “OS and storage” section:

GCP Image And Disk Space for LLaMA 3.1 405B

Installing vLLM

vLLM, which stands for Virtual Large Language Model, represents a significant advancement in the field of AI, particularly in how large language models (LLMs) are served and utilized for inference.

vLLM is engineered for high-throughput and low-latency inferences, making it ideal for applications where quick and efficient language processing is crucial. It achieves this through innovative techniques like PagedAttention, which optimizes memory usage by managing attention key and value memory more efficiently, allowing for up to 24x higher throughput compared to traditional methods like HuggingFace Transformers.

The core of vLLM’s efficiency lies in its memory management. By using PagedAttention, vLLM divides the key-value (KV) cache into blocks, which allows for better memory utilization and reduces fragmentation, a common bottleneck in GPU memory usage for LLMs. This approach not only speeds up processing but also allows for handling more requests simultaneously without significant performance drops.

As an inference and serving engine, vLLM focuses on not just running LLMs but doing so in a way that maximizes resource utilization. It employs techniques like continuous batching of incoming requests, which ensures that the GPU remains fully utilized, thereby reducing idle times and increasing overall efficiency.

vLLM supports various quantization techniques (like GPTQ, AWQ, INT4, INT8, FP8) which reduce the precision of model weights, thereby decreasing memory usage and potentially speeding up inference.

Installing vLLM is relatively easy. Connect to the GCP VM instance, and install vLLM using pip:

pip install vllm

I am going to perform distributed inference on 8 x H100 GPUs, so I need to install Ray as well:

pip install ray

If you experience compatibility problems while installing vLLM, it may be simpler for you to compile vLLM from the source or use their Docker image: have a look at the vLLM installation instructions.

Inference Server for LLaMA 3.1 405B

Here is a basic Python example to test the model:

from vllm import LLM

# Load LLaMA 3.1 405B on 8 GPUs
llm = LLM("neuralmagic/Meta-Llama-3.1-405B-Instruct-FP8-dynamic", tensor_parallel_size=8)

print(llm.generate("What is the difference between fp8 quantization and int8 quantization?"))

You can run the Python script. If this is the first time you run it, you will need to wait for the model to be downloaded and loaded on the GPU, then you will receive a response like this:

FP8 (Floating-Point 8) and INT8 (Integer 8) are both quantization techniques used to reduce the precision of numerical values in deep learning models, but they differ in their representation and behavior.

**INT8 Quantization**

INT8 quantization represents numbers as 8-bit integers, which can take on values between -128 and 127 (or 0 and 255 for unsigned integers). This means that the precision of the numbers is limited to 8 bits, and any values outside this range are clipped or saturated.

INT8 quantization is a simple and widely used technique, especially for integer-based architectures like ARM and x86. Most deep learning frameworks, including TensorFlow and PyTorch, support INT8 quantization.

**FP8 Quantization**

FP8 quantization, on the other hand, represents numbers as 8-bit floating-point numbers, with 1 sign bit, 2 exponent bits, and 5 mantissa bits. This allows for a much larger dynamic range than INT8, with values that can be as small as 2^-14 or as large as 2^15.

FP8 quantization is a more recent development, and its main advantage is that it can provide better accuracy than INT8 quantization, especially for models that require a large dynamic range, such as those with batch normalization or depthwise separable convolutions. FP8 is also more suitable for models that are sensitive to quantization noise, like those with recurrent neural networks (RNNs) or long short-term memory (LSTM) networks.

**Key differences**

Here are the key differences between FP8 and INT8 quantization:

1. **Dynamic range**: FP8 has a much larger dynamic range than INT8, which means it can represent a wider range of values.
2. **Precision**: FP8 has a lower precision than INT8, with 5 mantissa bits compared to 8 bits for INT8.
3. **Behavior**: FP8 is more suitable for models that require a large dynamic range, while INT8 is better suited for models with smaller weights and activations.
4. **Hardware support**: INT8 is widely supported by most hardware platforms, while FP8 is still an emerging standard, with limited hardware support.

In summary, FP8 quantization offers better accuracy and a larger dynamic range than INT8 quantization, but it requires more sophisticated hardware support and may not be suitable for all models or applications.

The LLaMA 3.1 405B model has already been quantized in fp8 for vLLM by Neural Magic, so I do not need to perform the quantization again. I simply load the quantized model from the HuggingFace Hub.

The tensor_parallel_size parameter is set according to the number of GPUs on the machine.

This simple Python script is not a proper production server though. I will now start the inference server in order to consume many requests in parallel and maximize throughput:

python -m vllm.entrypoints.openai.api_server \
--model neuralmagic/Meta-Llama-3.1-405B-Instruct-FP8-dynamic \
--tensor-parallel-size 8

Once the model is loaded, you can start a second terminal and make some requests:

curl http://localhost:8000/v1/completions \
-H "Content-Type: application/json" \
-d '{
    "model": "neuralmagic/Meta-Llama-3.1-405B-Instruct-FP8-dynamic",
    "prompt": "Who are you?"
}'
I'm an artificial intelligence model known as Llama. Llama stands for "Large Language Model Meta AI."

Conclusion

LLaMA 3.1 405B is a cutting-edge generative AI model but deploying it into production is not easy.

The biggest challenge is to find the right hardware. GPUs are very costly and there is a global shortage. But once you manage to provision the right GPUs, deploying the model with an inference server like vLLM is quite easy.

For such large models, you might want to leverage quantization to reduce the VRAM usage and improve the latency, like I did. But be careful: quantization is not always a silver bullet as it can decrease the accuracy of the model.

Fine-tuning A Semantic Search Model With Sentence Transformers For A RAG Application

Implementing a Retrieval Augmented Generation (RAG) pipeline by fine-tuning your own semantic search model is a powerful approach to enhance the accuracy and relevance of question-answering systems.

This technique combines the strengths of both semantic search and generative AI, enabling the system to better understand user questions and generate more accurate and contextually relevant responses. By fine-tuning a semantic search model using Sentence Transformers, developers can tailor the model to their specific domain, improving the overall performance of the RAG pipeline.

Semantic Search

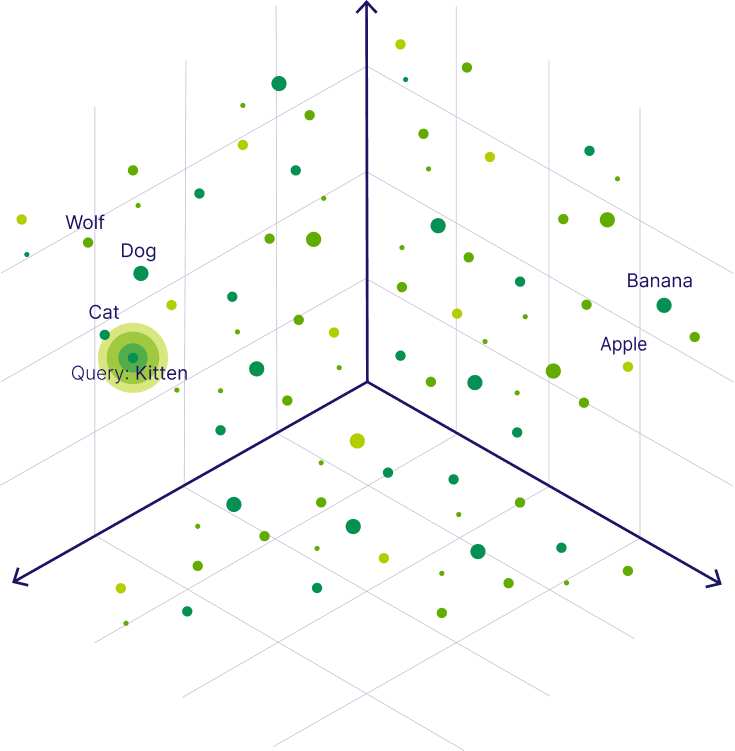
Semantic search is a data searching technique that goes beyond the traditional keyword-based search methods. It uses natural language processing and machine learning algorithms to improve the accuracy of search results by considering the searcher’s intent and the contextual meaning of the terms used in their query. This approach aims to understand the underlying meaning of the search query and the content on web pages, rather than simply matching keywords. By doing so, semantic search can deliver more relevant results, even if they don’t contain the exact words used in the original query.

To achieve this, semantic search employs various techniques, such as word-sense disambiguation, concept extraction, and query expansion. It also utilizes vector search and machine learning to return results that aim to match the user’s intent and context. Semantic search is widely used in web search engines, such as Google, and is powered by technologies like the Knowledge Graph, which stores structured data about entities and their relationships. This allows search engines to understand the meaning behind search queries and provide more accurate and meaningful results.

Semantic search is very useful to businesses who want to answer questions on their own domain knowledge like their technical documentation, contracts, product descriptions…

What Is Retrieval Augmented Generation (RAG)?

Retrieval Augmented Generation

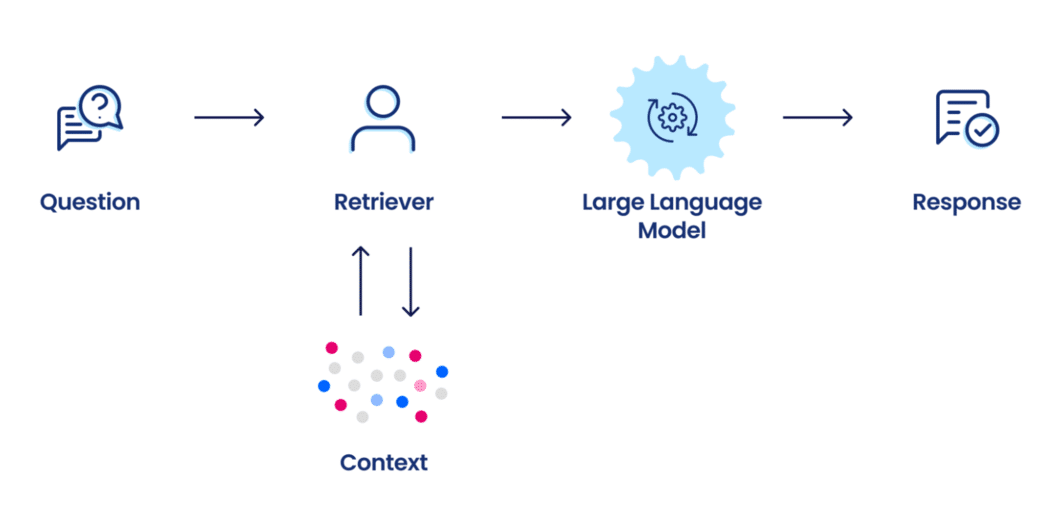
Retrieval Augmented Generation (RAG) is a technique that enhances the accuracy and reliability of generative AI models, such as Large Language Models (LLMs), by incorporating external data sources to provide more contextually accurate and up-to-date information. It integrates a retrieval component with a generative model, allowing the system to search and fetch relevant information from a database or knowledge base to supplement its internal knowledge when generating responses.

This approach ensures that the AI model can provide answers based on the most current, reliable facts and enables users to verify the sources of the information used in the model’s responses. RAG helps to ground the AI model on external sources of knowledge, improving the quality of its output and providing a way to update the model without the need for extensive retraining.

RAG is a great strategy to mitigate potential hallucinations from generative AI models. RAG helps build a question answering system that has the best of both worlds: factual accuracy and human responses generated in natural language.

What Is The Sentence Transformers Library?

The Sentence Transformers library is a powerful Python framework designed for state-of-the-art text embeddings. It is built upon transformer neural networks like BERT, RoBERTa, XLM-R, and others, achieving top performance in various tasks including semantic search, paraphrase mining, semantic similarity comparison, clustering, and more. This library allows for easy fine-tuning of sentence embedding methods, enabling the creation of task-specific sentence embeddings tailored to meet specific needs. Learn more on the Sentence Transformers website

The library offers a wide selection of pre-trained Sentence Transformers models for more than 50 languages, available on the Hugging Face platform. Users can also train or fine-tune their own models using the library, providing the flexibility to create custom models for unique use cases. The Sentence Transformers team recently released a new major version (v3) that considerably improves the capabilities of this library, especially its fine-tuning capabilities.

The Sentence Transformers library is fast, comprehensive, and well maintained, which is why I am using it in this tutorial.

Fine-Tuning Your Own Semantic Search Model

Fine-tuning (encoding) your own semantic search model is a great way to get accurate results while ensuring a very low latency. This is even more true if you deploy your fine-tuned semantic search model on a GPU.

First, I will make a small dataset. Create a 1-column CSV file (called “dataset.csv”) containing the following technical documentation about HP printers (in a real life scenario you will want to include many more examples of course):

"HP® LaserJets have unmatched printing speed, performance and reliability that you can trust. Enjoy Low Prices and Free Shipping when you buy now online."
"Every HP LaserJet comes with a one-year HP commercial warranty (or HP Limited Warranty)."
"HP LaserJet ; Lowest cost per page on mono laser printing. · $319.99 ; Wireless options available. · $109.00 ; Essential management features. · $209.00."

Each row can contain up to 512 tokens (roughly equivalent to 400 words), and in order to maximise accuracy it is recommended to stay below 128 tokens (roughly equivalent to 100 words). Now that I have these 3 pieces of documentation in the dataset, I can fine-tune/encode a model out of it, using Sentence Transformers. Create a Python script with the following (make sure that PyTorch and Sentence Transformers are installed).

from sentence_transformers import SentenceTransformer
import csv
import torch

model_name = 'paraphrase-multilingual-mpnet-base-v2'
encoded_model_path = 'semantic_search_model.pt'
dataset_path = 'dataset.csv'

bi_encoder = SentenceTransformer(model_name)

passages = []
with open(dataset_path) as csv_file:
    csv_reader = csv.reader(csv_file)
    for row in csv_reader:
        passages.append(row[0])
        
corpus_embeddings = bi_encoder.encode(
    passages, batch_size=32, convert_to_tensor=True, show_progress_bar=True)

torch.save(corpus_embeddings, encoded_model_path)

This script downloads and uses paraphrase-multilingual-mpnet-base-v2 as a base model and encodes a new semantic search model based on your new data. You can choose among many available pre-trained models, depending on your requirements (model size, use case, supported languages, …). Depending on your hardware you will want to adapt the “batch_size” parameter in order to speed up the encoding process.

Once created you can use your model for inference with the following Python script:

import csv
from sentence_transformers import SentenceTransformer, util
import torch

bi_encoder = SentenceTransformer('paraphrase-multilingual-mpnet-base-v2')
semantic_search_model = torch.load('semantic_search_model.pt')

passages = []
with open('app/custom_model/dataset.csv') as csv_file:
    csv_reader = csv.reader(csv_file)
    for row in csv_reader:
        passages.append(row[0])

question_embedding = bi_encoder.encode(
    "How long is the warranty on the HP Color LaserJet Pro?", convert_to_tensor=True)
hits = util.semantic_search(
    question_embedding, semantic_search_model, top_k=3)
hits = hits[0]

result = {"search_results": [
    {"score": hit['score'], "text": passages[hit['corpus_id']]} for hit in hits]}

The above inference script returns the following results:

{
"search_results": [
    {
        "score": 0.99,
        "text": "Every HP LaserJet comes with a one-year HP commercial warranty (or HP Limited Warranty)."
    },
    {
        "score": 0.74,
        "text": "All consumer PCs and printers come with a standard one-year warranty. Care packs provide an enhanced level of support and/or an extended period of coverage for your HP hardware. All commercial PCs and printers come with either a one-year or three-year warranty."
    },
    {
        "score": 0.68,
        "text": "In-warranty plan · Available in 2-, 3-, or 4-year extension plans · Includes remote problem diagnosis support and Next Business Day Exchange Service."
    },
    ]
}

In the inference script, the “top_k” parameter determines how many results I want to return. In the result, I show the matching text from the dataset with a confidence score. This score is important because it helps me decide whether I want to accept the response or not.

Generating a Response in Natural Language With Generative AI

As you could see, the main limitation of semantic search is that the model returns the raw text from the dataset without directly answering the question. So I now want to give this to a generative AI model as a context in order to answer the initial question in natural language.

I can easily achieve this by leveraging an advanced LLM like GPT-4 on OpenAI or LLaMA 3 and ChatDolphin on NLP Cloud. You can either decide to keep the best result from the semantic search model and pass this as a context to the LLM, or keep several results. Here is a prompt example using the best result only:

Context: Every HP LaserJet comes with a one-year HP commercial warranty (or HP Limited Warranty).
Based on the above context, answer the following question: How long is the warranty on the HP Color LaserJet Pro?

This request returns something like that:

The warranty on the HP Color LasertJet Pro lasts at least 1 year.

Fine-tuning a Semantic Search Model VS Storing Embeddings In a Vector Database

In a Retrieval-Augmented Generation (RAG) system, encoding a semantic search model and using a vector database are two interesting options.

Encoding a semantic search model involves training a neural network, often a transformer-based model, to understand and generate embeddings for textual data. On the other hand, a vector database is a specialized database designed to store, index, and query these high-dimensional vectors efficiently.

For businesses looking to achieve very low latencies, it is recommended to fine-tune your own semantic search model and deploy it on a GPU. However it is at the expense of flexibility as a new model has to be encoded every time the dataset changes. If your underlying data changes very frequently, it might be simpler for you to extract the embeddings and store them in a vector database (like PG Vector for example).

Conclusion

Retrieval Augmented Generation is crucial for businesses looking into answering questions about specific data like technical documentation, contracts, etc, as it considerably increases the accuracy of the results. RAG is a key component of a support chatbot for example.

Sentence Transformers is a great library that can be used to fine-tune your own semantic search model based on your own data. When deployed on a GPU and coupled with an advanced generative AI model, such a model proves extremely powerful.

How to Install and Deploy LLaMA 3 Into Production?

The LLaMA 3 generative AI model was released by Meta a couple of days ago, and it already shows impressive capabilities.

Learn how to install and deploy LLaMA 3 into production with this step-by-step guide. From hardware requirements to deployment and scaling, I cover everything you need to know for a smooth implementation.

Introduction to LLaMA 3

Meta has introduced initial versions of their Llama 3 open-source AI model, which can be utilized for text creation, programming, or chatbots. Furthermore, Meta announced its plans to incorporate LLaMA 3 into its primary social media applications. This move aims to compete with other AI assistants, such as OpenAI’s ChatGPT, Microsoft’s Copilot, and Google’s Gemini.

Similar to Llama 2, Llama 3 stands out as a freely accessible large language model with open weights, offered by a leading AI company (although it doesn’t qualify as “open source” in the conventional sense).

Currently, Llama 3 can be downloaded for free from Meta’s website in two different parameter sizes: 8 billion (8B) and 70 billion (70B). Users can sign up to access these versions. Llama 3 is offered in two variants: pre-trained, which is a basic model for next token prediction, and instruction-tuned, which is fine-tuned to adhere to user commands. Both versions have a context limit of 8,192 tokens.

In an interview with Dwarkesh Patel, Mark Zuckerberg, the CEO of Meta, mentioned that they trained two custom-built models using a 24,000-GPU cluster. The 70B model was trained with approximately 15 trillion tokens of data, and it never reached a point of saturation or a limit to its capabilities. Afterward, Meta decided to focus on training other models. The company also revealed that they are currently working on a 400B parameter version of Llama 3, which experts like Nvidia’s Jim Fan believe could perform similarly to GPT-4 Turbo, Claude 3 Opus, and Gemini Ultra on benchmarks like MMLU, GPQA, HumanEval, and MATH.

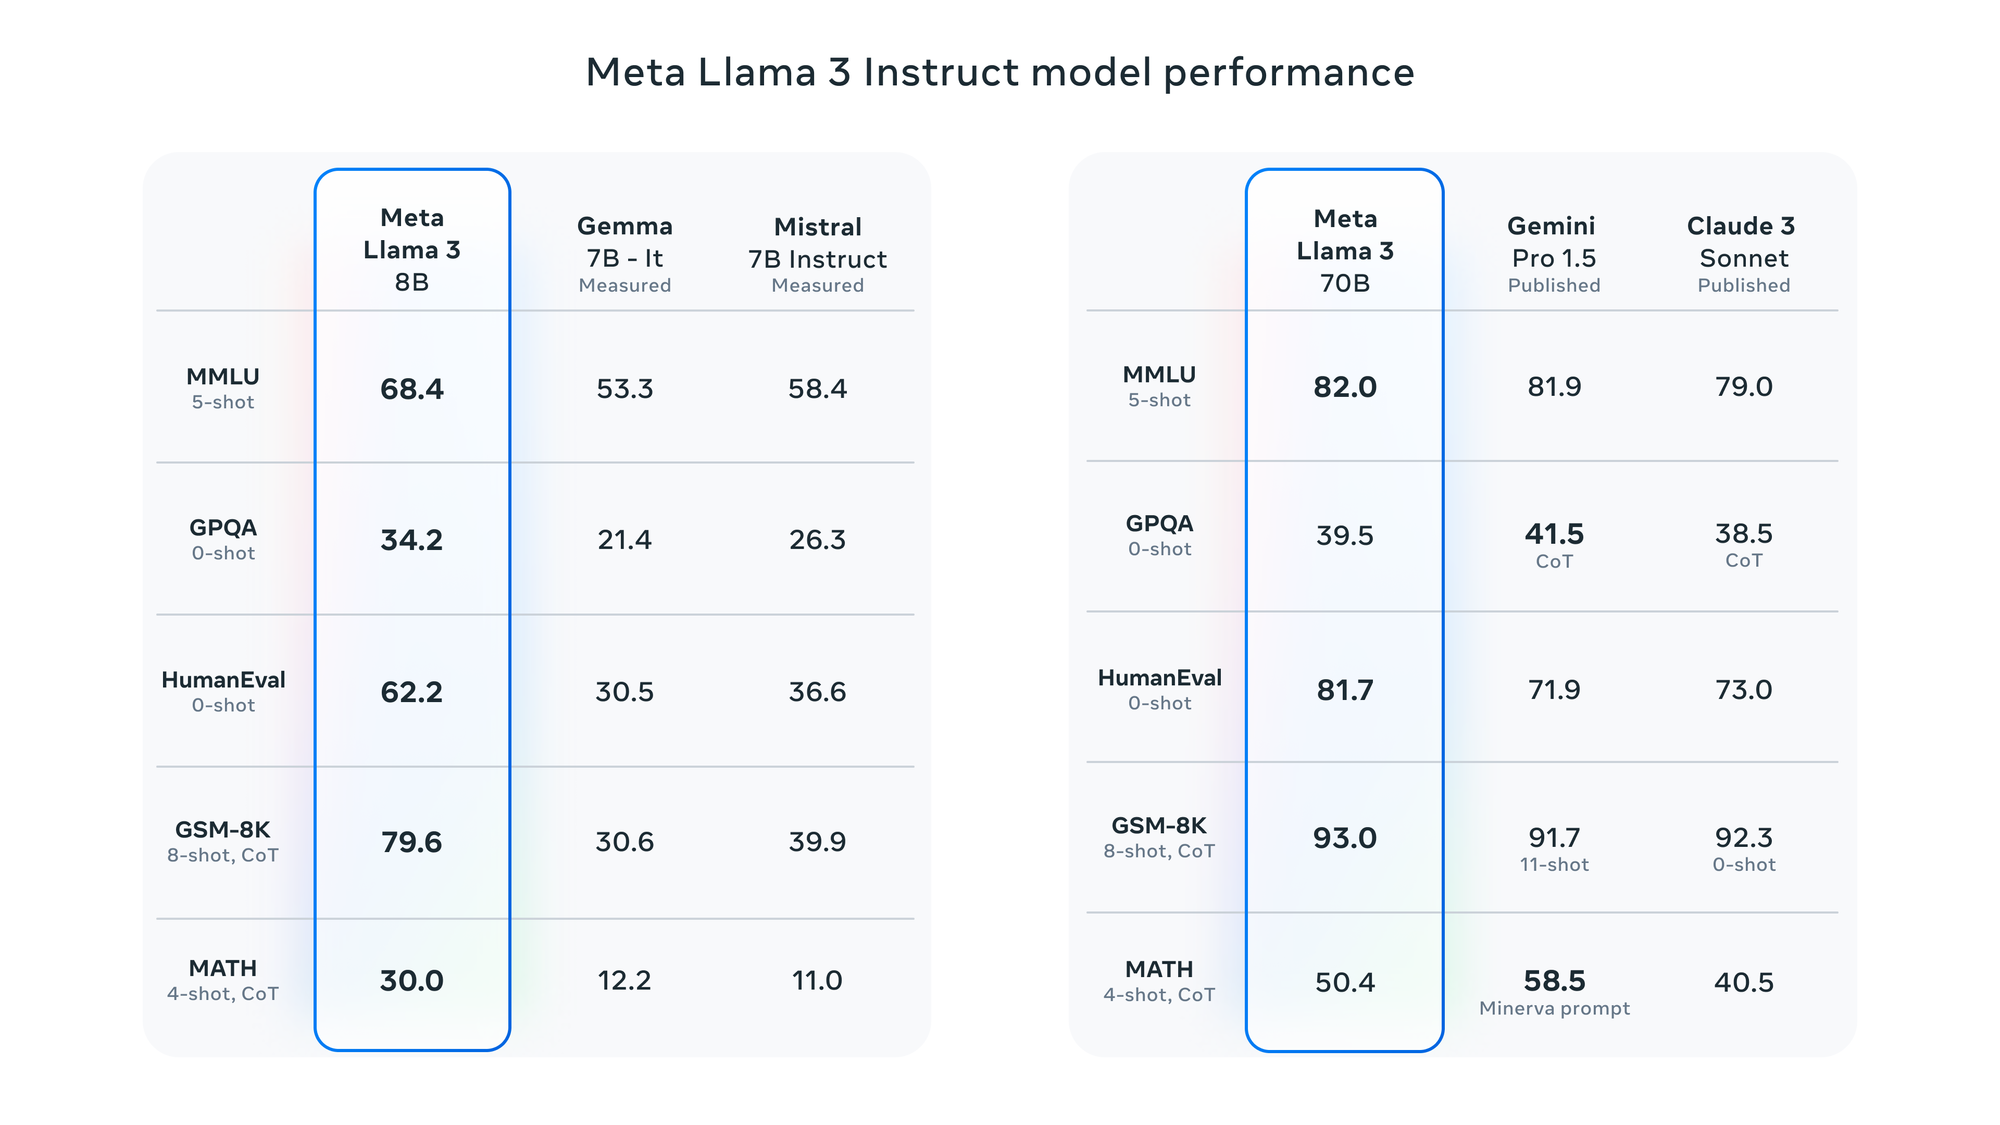
According to Meta, Llama 3 has been assessed using various benchmarks, including MMLU (undergraduate level knowledge), GSM-8K (grade-school math), HumanEval (coding), GPQA (graduate-level questions), and MATH (math word problems). These benchmarks demonstrate that the 8B model outperforms open-weights models such as Google’s Gemma 7B and Mistral 7B Instruct, and the 70B model is competitive against Gemini Pro 1.5 and Claude 3 Sonnet.

Meta reports that the Llama 3 model has been improved with the ability to comprehend coding, similar to Llama 2, and for the first time, it has been trained using both images and text. However, its current output is limited to text.

LLaMA 3 Benchmarks

LLaMA 3 Hardware Requirements And Selecting the Right Instances on AWS EC2

As many organizations use AWS for their production workloads, here is how to deploy LLaMA 3 on AWS EC2.

There are multiple obstacles when it comes to implementing LLMs, such as VRAM (GPU memory) consumption, inference speed, throughput, and disk space utilization. In this scenario, I need to make sure that I allocate a GPU instance on AWS EC2 with sufficient VRAM capacity to run the models.

LLaMA 3 8B requires around 16GB of disk space and 20GB of VRAM (GPU memory) in FP16. You could of course deploy LLaMA 3 on a CPU but the latency would be too high for a real-life production use case. As for LLaMA 3 70B, it requires around 140GB of disk space and 160GB of VRAM in FP16.

Getting your hands on 20GB of VRAM for LLaMA 3 8B is fairly easy. I recommend that you provision an NVIDIA A10 GPU: this GPU comes with 24GB of VRAM and it is a fast GPU based on the Ampere platform. On AWS EC2, you should select a G5 instance in order to provision an A10 GPU. A g5.xlarge will be enough.

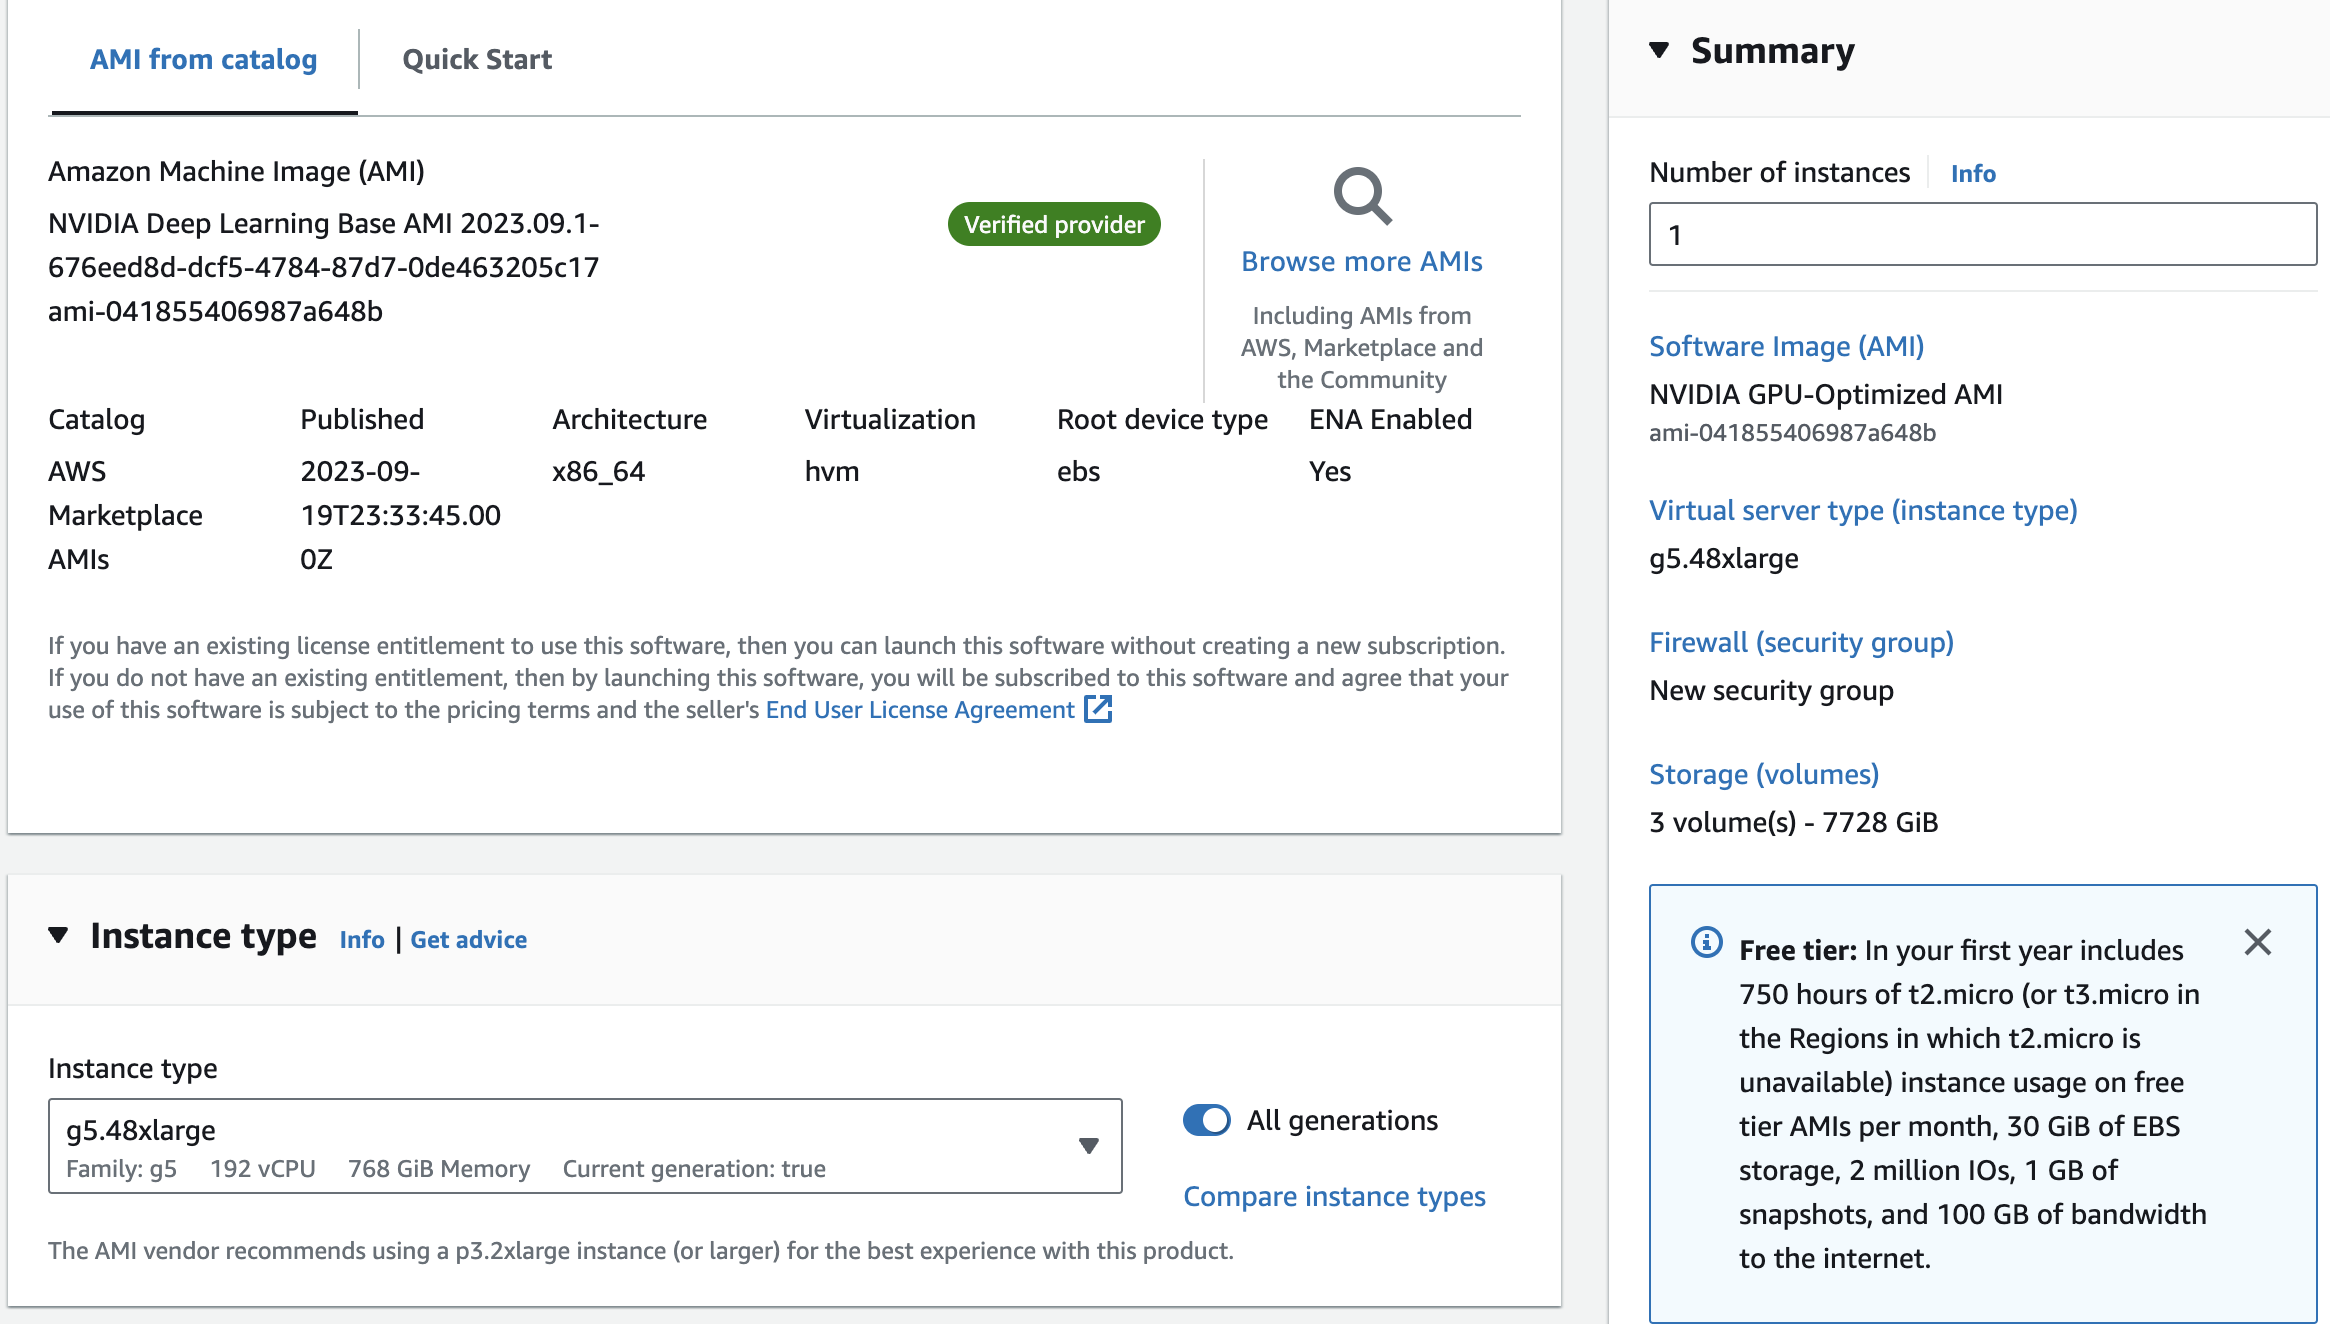
Deploying the LLaMA 3 70B model is much more challenging though. No GPU has enough VRAM for this model so you will need to provision a multi-GPU instance. If you provision a g5.48xlarge instance on AWS you will get 192GB of VRAM (8 x A10 GPUs), which will be enough for LLaMA 3 70B.

In such a configuration, you can expect the following latencies (response times): 50 tokens generated in 1 second for LLaMA 3 8B, and 50 tokens generated in 5 seconds for LLaMA 3 70B.

In order to decrease the operating cost of these models and increase the latency, you can investigate quantization techniques but be aware that such optimizations can harm the accuracy of your model. Quantization is out of the scope of this article.

In order to provision such instances, log into your AWS EC2 console, and launch a new instance: select the NVIDIA deep learning AMI, on a g5.xlarge or g5.48xlarge instance. Do not forget to provision enough disk space too.

Deep Learning AMI on G5 instance on AWS

Production Inference With vLLM

vLLM is a library designed for rapid and easy LLM inference and deployment. Its efficiency is attributed to various sophisticated methods, including paged attention for optimal management of attention key and value memory, real-time processing of incoming queries in batches, and personalized CUDA kernels.

In addition, vLLM provides a high degree of adaptability by employing distributed computation (using tensor parallelism), real-time streaming, and compatibility with both NVIDIA and AMD graphics cards.

Specifically, vLLM will greatly aid in deploying LLaMA 3, so I can use AWS EC2 instances equipped with several compact NVIDIA A10 GPUs. This is advantageous over using a single large GPU, such as the NVIDIA A100 or H100. Furthermore, vLLM will significantly enhance the model’s efficiency through continuous batch inference.

Setting up vLLM is quite simple. Establish an SSH connection to the AWS instance you just created, and install vLLM using pip:

pip install vllm

Since I plan to perform distributed inference using vLLM on 8 x A10 GPUs, the installation of Ray is required as well:

pip install ray

In case you encounter compatibility problems while installing, it may be simpler for you to compile vLLM from the source or use their Docker image: have a look at the vLLM installation instructions.

Launch the Inference Server

Here is the Python inference script:

from vllm import LLM

# Use LLaMA 3 8B on 1 GPU
llm = LLM("meta-llama/Meta-Llama-3-8B-Instruct")

# Use LLaMA 3 70B on 8 GPUs
# llm = LLM("meta-llama/Meta-Llama-3-70B-Instruct", tensor_parallel_size=8)

print(llm.generate("What are the most popular quantization techniques for LLMs?"))

You can run the above script. If this is the first time you run this script, you will need to wait for the model to be downloaded and loaded on the GPU, then you will receive something like this:

The most popular quantization techniques for Large Language Models (LLMs) are:
1. Integer Quantization
2. Floating-Point Quantization
3. Mixed-Precision Training
4. Knowledge Distillation

It’s quite simple to understand. You simply need to adjust the tensor_parallel_size according to the number of GPUs that you possess.

The next step is an inference server capable of managing numerous requests and executing simultaneous inferences. To begin, start the server:

For LLaMA 3 8B:

python -m vllm.entrypoints.openai.api_server \
--model meta-llama/Meta-Llama-3-8B-Instruct

For LLaMA 3 70B:

python -m vllm.entrypoints.openai.api_server \
--model meta-llama/Meta-Llama-3-70B-Instruct
--tensor-parallel-size 8

It should take up to 1 minute for the model to load on the GPU. Then you can start a second terminal and start making some requests:

curl http://localhost:8000/v1/completions \
-H "Content-Type: application/json" \
-d '{
    "model": "meta-llama/Meta-Llama-3-8B-Instruct",
    "prompt": "What are the most popular quantization techniques for LLMs?"
}'

You now have a proper production ready inference server that can handle many parallel requests thanks to continuous batching. At some point, if the number of requests is too high, the GPU will be overloaded though. In that case you will need to replicate the model on several GPU instances and load balance your requests (but this is out of the scope of this article).

Conclusion

As you can see, deploying LLaMA 3 into production does not require any complex code thanks to inference servers like vLLM.

Provisioning the right hardware is challenging though. First because these GPUs are very costly, but also because of the current global GPU shortage. If this is your first time trying to provision a GPU server at AWS you might not have the permission to create a GPU server. In that case you will need to contact support and explain your use case. In this article I used AWS EC2 but other vendors are available of course (Azure, GCP, OVH, Scaleway…).